How to share context between your team's AI agents
Between teammates' machines, context travels as files. In Claude Code, a committed CLAUDE.md, .claude/rules/ and project skills reach every teammate through git, while auto memory, CLAUDE.local.md and session transcripts stay on the machine that wrote them, and cross-session messaging only reaches your own sessions. So put shared context in files: commit the project rules, write a handoff note for work in progress, and keep notes that people outside engineering also edit in a folder that syncs to every machine.
Short answer
Teams that run AI agents on several laptops hit the same wall. One person's agent knows the pricing rationale, another's knows the migration plan, and neither knows what the other knows. The context exists. It's trapped on whichever laptop produced it.
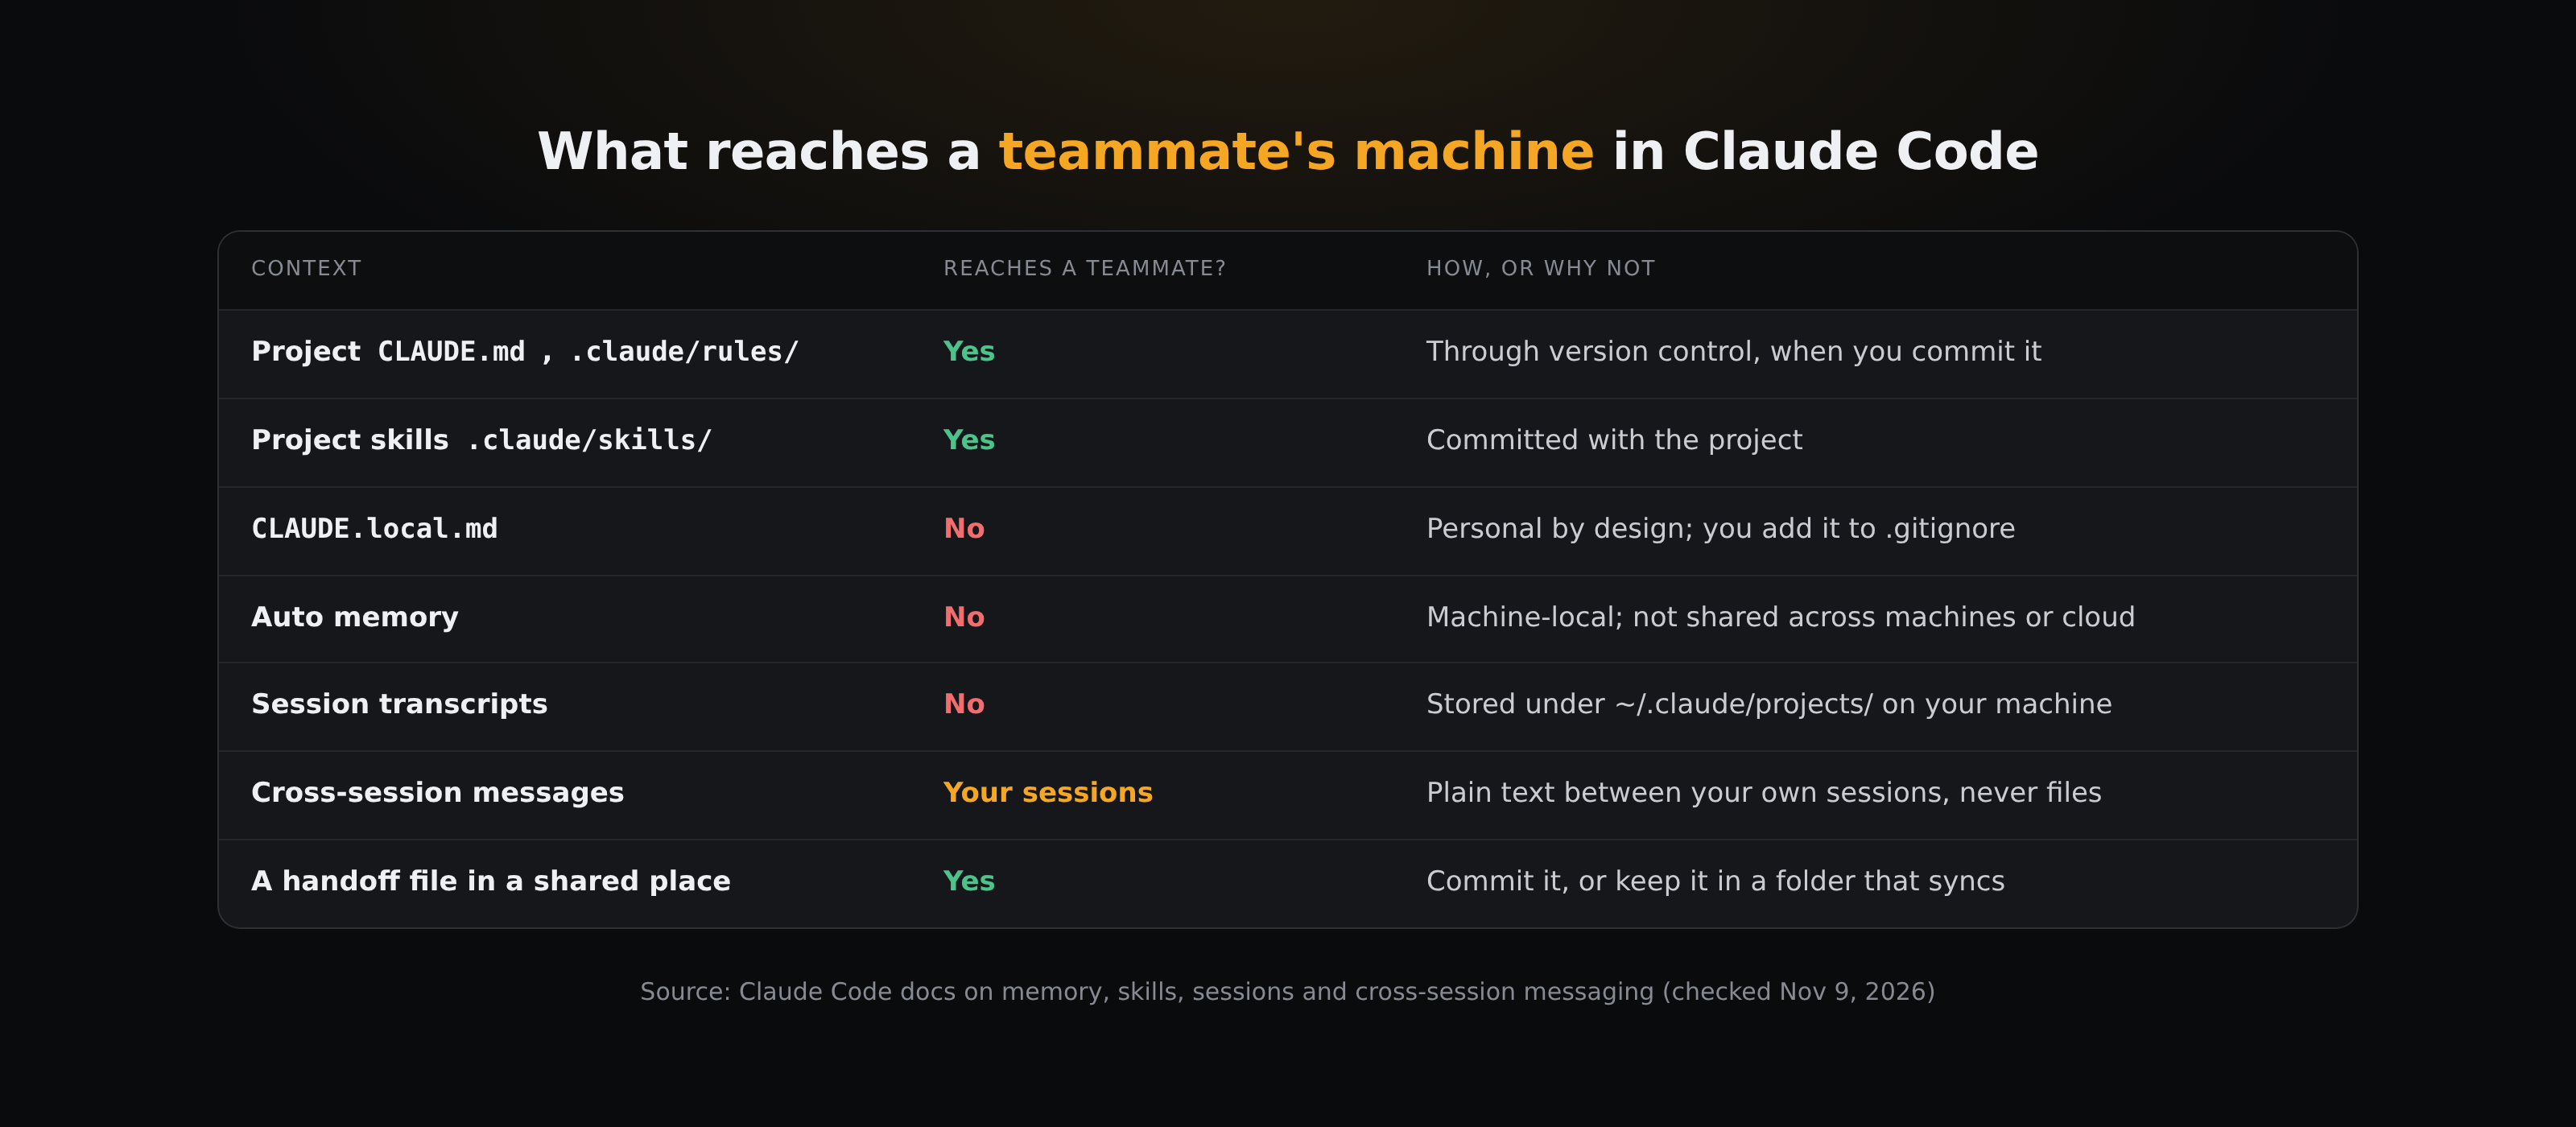
The rule that explains most of it: between teammates' machines, context travels as files. Claude Code's personal memory (auto memory, CLAUDE.local.md, transcripts) stays on one machine, so anything you want a teammate's agent to know has to end up in a file that reaches their disk, through git or through a folder that syncs. The table above shows which parts of Claude Code do that, checked against Anthropic's documentation on November 9, 2026.
What in Claude Code reaches a teammate's machine?
From the Claude Code memory docs:
- Project instructions (
./CLAUDE.mdor./.claude/CLAUDE.md) are, in the docs' words, "Team-shared instructions for the project" that reach "Team members via source control". The same goes for rule files in.claude/rules/and project skills in.claude/skills/: they travel when you commit them. CLAUDE.local.mdis for personal, project-specific preferences. The docs tell you to add it to.gitignore, so it stays with you.- Auto memory, the notes Claude takes on its own in
~/.claude/projects/<project>/memory/, is "machine-local". In the docs' words: "Files are not shared across machines or cloud environments." - Session transcripts live as
.jsonlfiles under~/.claude/projects/on your machine. You can resume your own sessions, but the sessions docs don't describe resuming one from someone else's machine. - Cross-session messaging lets Claude message your other Claude Code sessions, on this machine or on your other machines through Remote Control. A message is "a piece of text one Claude writes to another, never the sender's conversation history or files."
- Agent teams are experimental and off by default. One lead session spawns and coordinates teammates, and a team is scoped to that session: "You can't create additional named teams or share a team across sessions."
So for two people on two laptops, the built-in path is the committed project files. Everything else has to be written down somewhere both machines can read.
Where should shared context live?
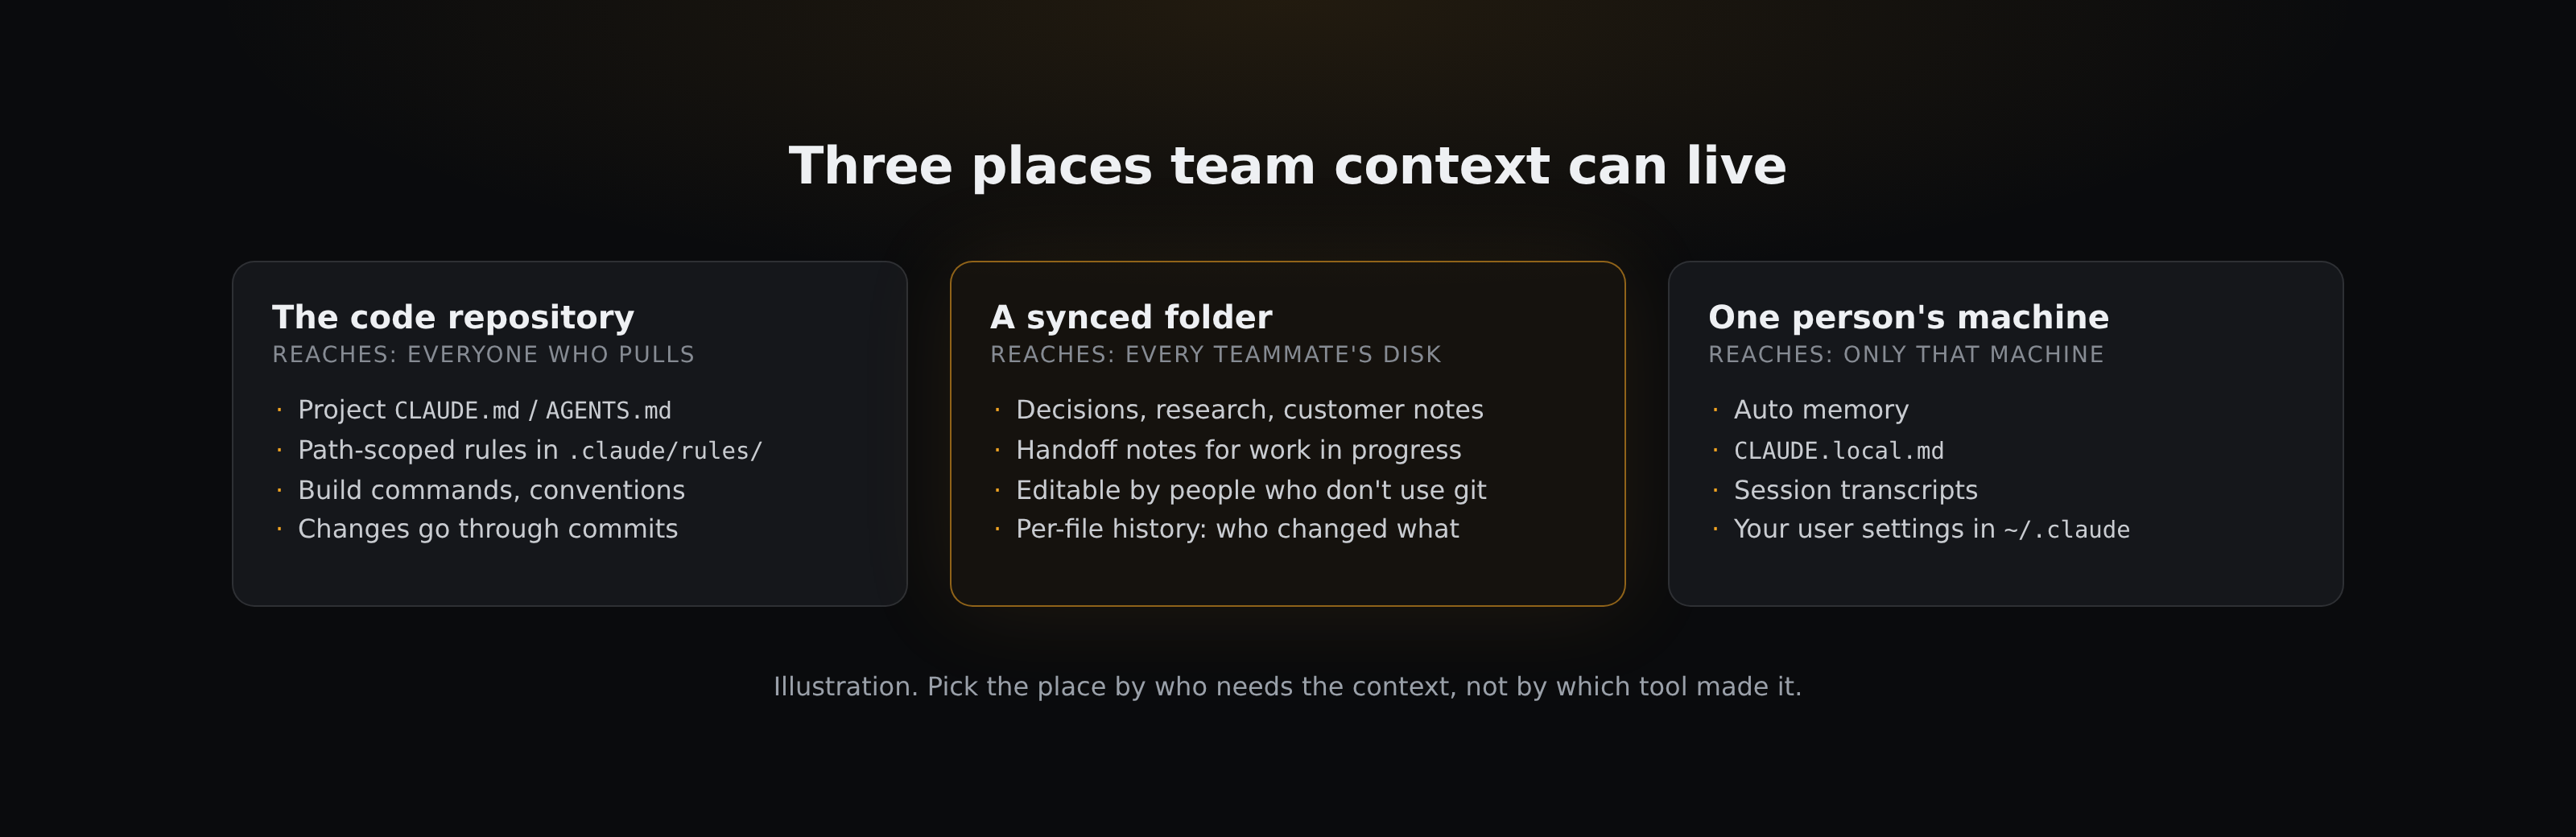
Pick the place by who needs the context:
- In the code repository, when the context is about the code: build commands, conventions, architecture, path-scoped rules. Anthropic suggests keeping each CLAUDE.md under 200 lines and moving procedures into skills or rules. Codex reads AGENTS.md before doing any work, and Claude Code can load an AGENTS.md too.
- In a folder that syncs to every machine, when the context isn't code: decisions and why they were made, research, customer notes, handoff notes for work in progress. These are often written by people who don't use git, and a workflow that requires a pull request keeps them out.
- On one machine, for what really is personal: your auto memory, your CLAUDE.local.md, your sandbox URLs.
You can connect the first two. Claude Code reads CLAUDE.md files from an extra folder if you add it with --add-dir and set CLAUDE_CODE_ADDITIONAL_DIRECTORIES_CLAUDE_MD=1, for example CLAUDE_CODE_ADDITIONAL_DIRECTORIES_CLAUDE_MD=1 claude --add-dir ../team-context. A CLAUDE.md can also pull in another file with @path/to/file; an import that points outside your working directory asks for approval the first time.
How do I hand off work to a teammate's agent?
Write the state of the work into a file, put it where their agent will read it, and tell them its name. A good handoff note is short and covers four things:
- what is done,
- what is left,
- the decisions made and why,
- the exact next step.
Ask your agent to write it before you stop ("Write handoff/search-rewrite.md: done, left, decisions and why, next step. Under 40 lines."), and your teammate starts with "Read handoff/search-rewrite.md and continue." Unlike a conversation, the note is reviewable, stays on disk after compaction, and works whichever agent your teammate uses.
Where the note lives decides how it travels. Committed to a branch, the teammate gets it on their next pull. In a synced folder, it is on their disk without a commit.
When the agents are services, not people's sessions, look at the Agent2Agent (A2A) protocol. It is an open protocol for agents built on different frameworks to delegate tasks and exchange information, originally developed by Google and now under the Linux Foundation. Its own docs say it is "Not a sub-agent or tool-call protocol" and not a replacement for MCP. It fits best when a deployed agent hands a task to another deployed agent. For a teammate picking up where your coding session stopped, a written note is the simpler tool.
What does a shared folder actually buy you?
The agent-facing part is that reads need no MCP server or API: the files are on disk, and the agent opens them with the same file tools it uses on code. An agent that can read a folder can also write to it, so the summary your agent produced at 2pm can be on your colleague's disk before their next session starts.
The human-facing part matters just as much. Someone outside engineering can open the folder on their Mac or Linux machine (or upload in the web app), drop in a PDF and fix a paragraph, and the same content reaches every agent on the team.
The part people underestimate is versioning. Shared context goes stale. Over time, the question becomes less "what does this document say" and more "is this still true, and who changed it." Per-file history with names and times turns an old wiki into something you can check.
What's the catch?
- Concurrent edits. Two people edit the same file offline and both come back online. Know what your tool does there before you adopt it: keep both versions, or silently pick one.
- Scope. A folder that syncs everything eventually syncs something that shouldn't leave a laptop. You want to sync part of a folder, not only all of it.
- Settings don't travel the same way. Instructions are files; settings and hooks are often per machine. If you point Claude Code's
autoMemoryDirectoryat a shared folder, that setting has to be present on each machine.
How BearDrive handles this
BearDrive is our answer to this problem: you mount a folder with bdrive init, and it stays in sync across every device and teammate through a hub. It is open source (AGPL-3.0). On the points above:
- Fresh before every turn.
bdrive initregisters hooks for Claude Code, Codex, Gemini CLI and Hermes that pull before the agent answers your message and push after it edits a file (Codex hooks are experimental and need turning on once). A handoff note your colleague's agent just wrote is on your disk before your agent's next turn. - Who changed what. Every change is recorded with account, time and device (
bdrive log, and History in the web app), andbdrive restorebrings back an earlier version.bdrive sync --notestamps a note, such as an agent session id, onto the changes it records. - Conflicts. Concurrent edits resolve as last-writer-wins, and the losing version is kept as a
name.bdrive-conflict-<device>-<time>file. - Scope. A gitignore-style
.bdriveignoreopts files out, andbdrive init . --only wiki,docssyncs only some subfolders. - What it won't sync.
.gitdirectories (keep code in git) and agent hook configuration such as.claude/settings.jsonand.mcp.json. Skills, commands and agents under.claude/do sync. BearDrive isn't built to move Claude Code conversations between machines: the handoff note is the thing that travels.
Questions
- How do I share context between Claude Code sessions on different teammates' machines?
- Through files that reach both machines. Commit the project CLAUDE.md, .claude/rules/ and .claude/skills/ for code context. For work in progress and notes outside the code, write a handoff file and keep it in the repo or in a folder that syncs to every teammate. Auto memory, CLAUDE.local.md and session transcripts stay on the machine that made them.
- Can teammates share Claude Code's auto memory?
- Not by default. Anthropic's docs call auto memory machine-local: it isn't shared across machines or cloud environments. You can move it with the autoMemoryDirectory setting, but it holds notes Claude took from one person's corrections. For context the whole team should rely on, a file someone wrote on purpose is clearer.
- How can one AI agent hand off work to another teammate's agent?
- Have the first agent write a short handoff note (done, left, decisions and why, next step) where the second agent will read it: a committed branch or a synced folder. When the agents run as services, the open A2A protocol defines how one agent delegates a task to another.
- Can two AI agents share the same memory?
- Yes, if the memory is files rather than a vendor's internal store. Coding agents read plain files from the working directory, so a folder that syncs to each machine gives Claude Code, Codex and others the same files to read with no integration between the agents.
- Do I need an MCP server to give an agent shared context?
- No. MCP is the right answer when the data lives in a system the agent can't reach, such as a database, a ticket tracker or an API. For markdown and documents, files on disk are simpler, work offline and need no server running.